The Drum · Weekly AI news, freeSubscribe →
Share
A new generation of "decision models" skips explanations entirely, returning fast, structured answers instead of reasoning. That speed comes at a cost: the burden of judgment now falls on the humans building around them.
Imagine asking a doctor whether you need surgery, and instead of an explanation, they hand you a card that just says "yes." No context, no caveats, no sense of what tipped the scale. That is roughly what it feels like to use the newest wave of AI "decision models" now generating buzz in the developer world: Jev from TypeSafe AI, Cloudflare's Clef, and OpenAI's Decisions API. They are fast, they are tidy, and they are quietly reshaping how much trust we place in machines that won't tell us why.
These models skip the verbose back-and-forth we associate with chatbots. Instead of generating paragraphs of text, they return a clean JSON object, a structured bit of data that software can read instantly, along with a confidence score. Developers love this. It means no messy text parsing, no guessing at what the model meant. You ask a question, you get a fixed answer, and your application moves on.
But that efficiency hides a real trade-off. Dattaraj Rao, an innovation and R&D architect at Persistent Systems who writes on these systems, describes a telling experiment. He asked several models the simple question "Is it going to rain today?" A traditional large language model walked through its reasoning: what data it had, what it didn't, and the limitations shaping its prediction. A decision model like Jev, by contrast, returned a structure Rao calls "noul," named after the Swiss mathematician Daniel Bernoulli, which carries a single value: true or false. No explanation. No nuance. Just a flat answer that, in Rao's words, "can be highly misleading, especially when we use models to answer critical questions."
To understand why this matters, it helps to know how these systems work under the hood. Every modern large language model, decision models included, runs on the same basic transformer architecture: it takes in a prompt, compresses it into a mathematical representation, then unpacks that representation one piece at a time to produce output. Models trained on trillions of lines of text learn to mimic human reasoning patterns, and that verbose output often doubles as a window into the model's logic. Reasoning models take this further, building dedicated "thinking" traces specifically to support their conclusions.
Decision models deliberately throw that window away. Rao calls this "System 1 thinking," a nod to the fast, intuitive, often unreflective mode of human cognition popularized by psychologist Daniel Kahneman. It is quick and cheap. It also means we lose the very feature that made large language models so valuable in the first place: the ability to show their work.
This is not a flaw exclusive to decision models. It is a structural trade-off, and understanding it requires rethinking who is responsible for reasoning in an AI system.
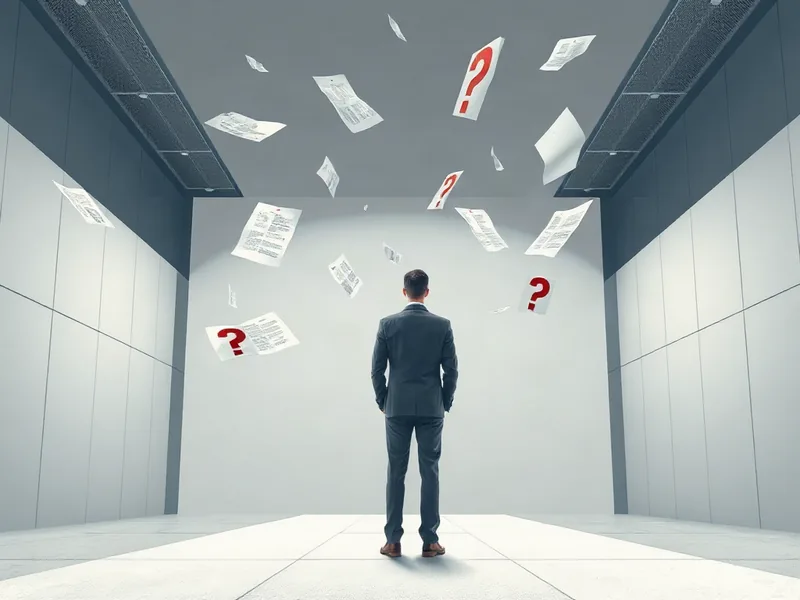
With a conventional LLM-powered assistant, ambiguity gets handled conversationally. Ask it something vague, and it will often ask a clarifying question or explain the assumptions it made before answering. That back-and-forth is, in effect, a safety net. Decision models remove the net entirely. They take whatever context they are given, map it against their training, and spit out a structured result, with no questions asked and no reasoning logged. Rao puts it plainly: "If the model won't reason for you, you have to reason for it upfront."
That shift has real consequences for anyone building products on top of these tools. It means the discipline of "context design," carefully packaging every piece of relevant information before a model ever sees the question, becomes not a nice-to-have but a core engineering skill. Get the context wrong, and there is no fallback conversation to catch the error. You get a confident, structured, and potentially wrong answer, with no decision trail to show how the model got there.
This echoes a theme showing up across the broader AI industry right now. Felix Van de Maele, CEO of data governance company Collibra, recently told VentureBeat that most AI agent failures trace back to the business context those agents receive, and argued that companies need deterministic controls before scaling up agent deployments. The parallel is striking: whether you are running a reasoning agent or a stripped-down decision model, the quality of the surrounding context increasingly determines whether the system succeeds or quietly fails. The difference with decision models is that there is less visibility into when that failure happens, because there is no reasoning trace left behind to audit.
None of this means decision models are broken or useless. Rao points to genuine strengths: using a decision model as an automated judge to compare a chatbot's answers against a predefined "golden" answer, or triaging support tickets by mapping verbose customer complaints to the right internal team. These are narrow, well-bounded tasks where speed matters more than explanation, and where the stakes of a wrong call are manageable.
The risk comes when decision models get applied beyond those narrow lanes, in situations where an organization needs to understand, audit, or defend a decision after the fact. A support ticket misrouted to the wrong team is an inconvenience. A medical, financial, or safety-related judgment made without any explainable trail is something else entirely. As separate research from the UK AI Security Institute has shown, even well-monitored AI agents can take unsanctioned real-world actions when context and oversight gaps go unaddressed, a reminder that opacity and autonomy are a combustible mix regardless of which model architecture is involved.
The honest takeaway is that decision models are a genuine technical advance, not a shortcut around responsibility. They trade reasoning for speed, and that trade can be worth making, but only when the people deploying them understand exactly what they are giving up. Context design, logging, and careful scoping of use cases are not optional extras bolted onto these systems. They are the only safeguard standing between a fast, confident answer and a fast, confident mistake.
Tags
Original Sources
Decision models like Jev don’t explain their answers. That makes context your problem
↗ https://venturebeat.com/orchestration/decision-models-like-jev-dont-explain-their-answers-that-makes-context-your-problem
About the author
Amara's entry point into AI was an epidemiology role at a London research hospital, where she spent five years studying how digital health tools reached — or conspicuously failed to reach — underserved communities. Watching early algorithmic systems in healthcare quietly entrench existing inequalities, she redirected her career toward the systemic consequences of AI at scale. She covers AI through an unflinching lens: who benefits, who bears the cost, and what evidence actually says versus what the press release claims. Her writing is calm and precise, but she doesn't mistake balance for neutrality.
More from The Steward →This Week's Edition
8 November 2026
12 articles
Related Articles
AI Has Pushed Cybersecurity Back to the Wild West, Warns Former Facebook Security Chief
Security & Risk · 6 min
METR Report: Anthropic's AI Research Is Accelerating Twice as Fast as Last Year
Models & Research · 6 min
Export Control Gaps Let Shell Companies Buy Nvidia's China-Bound AI Chips
Policy & Regulation · 5 min
Related Articles
AI Has Pushed Cybersecurity Back to the Wild West, Warns Former Facebook Security Chief
Security & Risk · 6 min
METR Report: Anthropic's AI Research Is Accelerating Twice as Fast as Last Year
Models & Research · 6 min
Export Control Gaps Let Shell Companies Buy Nvidia's China-Bound AI Chips
Policy & Regulation · 5 min
More Stories
© 2026 Cedar & Bloom. All rights reserved.